Agent memory needs its OpenTelemetry moment
Count the memory formats on your machine
List every place your coding tools keep something they "remember". A typical setup today:
- an
AGENTS.mdorCLAUDE.mdin most repos, and.cursor/rules/*.mdcin a few - an agent writing files to a
/memoriesdirectory through Anthropic's memory tool - Copilot keeping facts about each repo on GitHub's side
- a memory MCP server keeping a JSONL knowledge graph
That's four different shapes, and none of them can read the others. A lesson your CI agent learns stays in whatever wrote it. Your editor agent can't read it, and neither can the next tool you try.
Each format is reasonable on its own. Together, they rebuild the same small idea again and again: a note an agent left for its future self, stored at some address, true for a while.
And the list keeps growing. Browse r/ClaudeAI, r/LocalLLaMA or r/cursor and you'll find a steady stream of "I built a memory layer for my agent" posts, each with its own storage, its own schema and its own MCP tools. That's good evidence the problem is real: people keep hitting it badly enough to build something. But every new solution adds one more format that nothing else can read. The problem isn't a missing tool. It's a missing agreement, and that only comes from the community working on it together.
I build one of these tools, LoreKit, which is open source. This isn't a pitch that LoreKit has solved memory. Its format is one proposal among several, with gaps of its own. The point is that this is the moment to agree on a shared shape, and that another field has already shown how.
We've seen this before
Before 2019, every observability vendor shipped its own agent, its own instrumentation library and its own data format. Switching vendors meant instrumenting your code again. Two open projects, OpenTracing and OpenCensus, tried to fix that and competed with each other too.
In 2019 they merged into OpenTelemetry. What mattered was what the vendors agreed to stop competing on:
- A data model: what a span, a metric and a log record are.
- Semantic conventions: shared names like
service.nameandhttp.*. - A protocol: OTLP, one way to send the data.
- Reference implementations: shared SDKs and the Collector.
Vendors kept competing on what they do with the data: storage, querying, analysis. Users instrument once. I work with OpenTelemetry every day at Dash0, and that agreement is why a whole ecosystem of tools can read each other's data.
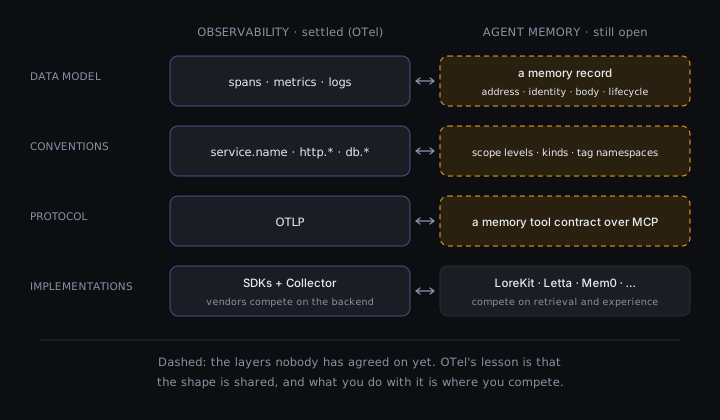
Agent memory is where observability was before 2019. The timing is good: the formats are young enough to change, and there's already a neutral home for agent standards. MCP and AGENTS.md both sit under the Linux Foundation's Agentic AI Foundation.
A tour of the shapes
These change quickly, so treat the details as a snapshot from late 2026.
| Family | Example | The unit of memory | Addressed by | Forgetting |
|---|---|---|---|---|
| Instruction files | AGENTS.md, CLAUDE.md, Cursor .mdc rules | A whole Markdown file | File path (plus globs for Cursor) | Never. A person edits it |
| Agent-managed files | Anthropic's memory tool | A file under /memories | A path the model picks | Never, unless the model deletes it |
| Hosted repo facts | GitHub Copilot Memory | A fact with code citations | One repository | Deleted after 28 days unused |
| Context blocks | Letta core memory | A labeled block with a character limit | A label on an agent | Never. Always in context |
| Extracted facts | Mem0 | A fact the service extracts from messages | user_id / agent_id / run_id / app_id | Optional expiration date |
| Namespaced store | LangGraph BaseStore | A JSON value dict | A namespace tuple + key | Optional TTL, reset when the item is read (by default) |
| Knowledge graph | MCP reference memory server | Entities, relations, observations | Entity name | Never |
| Temporal graph | Graphiti / Zep | A fact on a graph edge | Entities + edge | Facts are invalidated rather than deleted, on two timelines |
| Addressed record | LoreKit | A record with a scope, key and lifecycle | A scope string + key | Never, unless a TTL is set |
A few of them got something right that a shared spec should keep. Copilot Memory pairs citations you can check against the code with forgetting by default, though it's locked inside one product. LangGraph shows how small the core can be: put(namespace, key, value). Graphiti models time properly, with separate timelines for when a fact was true and when it was recorded. And AGENTS.md shows that a plain file at a known path can become a standard.
The proposals that already exist
Several people have started on this. MacPaw Research's Portable Memory is a .mem bundle with byte-reproducible serialization, deletion tombstones and optional signing; its authors say it isn't widely adopted yet. The Open Memory Protocol is an April 2026 draft for moving conversations and the memories derived from them between platforms as a ZIP with a manifest. Cognee's COGX format imports from Mem0, Letta and Zep.
These mostly solve export: moving one person's memory from vendor A to vendor B. Coding tools also have a second, open problem: live addressing. When a CI job, an editor agent and a review bot work in the same repo at once, how do they read and write the same place and agree on what it means? A complete spec needs both.
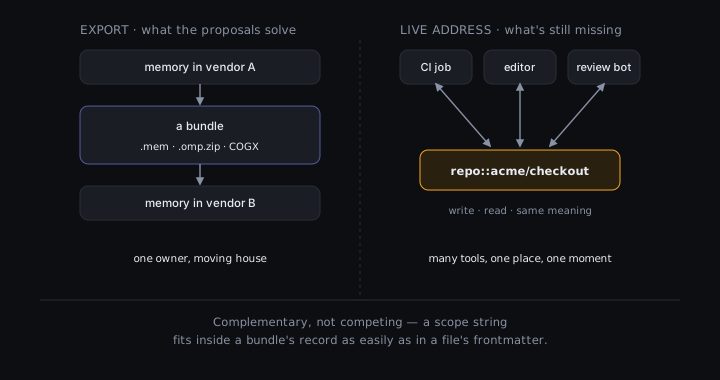
Strip away the branding and every format answers the same four questions differently: where a memory is true, what its identity is (does a second write update it or duplicate it?), what it says, and when it stops being true. Nobody disagrees that those matter. The tools only disagree on the answers, which is where OpenTelemetry started too.
There's one real fork: who writes the memory. In instruction files it's a person. In the memory tool, Letta and LoreKit, it's the model. In Mem0 and Graphiti, a service extracts facts from the conversation. A spec doesn't need to pick one. It needs to record which, so a reader knows how much to trust what it reads.
Here's roughly what one record could look like as a file. It illustrates the data model; the field names aren't a proposal:
---
spec: agent-memory/0.1
id: 8f0c2a6e-4b1d-4c7a-9e2f-3a5b6c7d8e9f
address: { level: repo, value: github.com/acme/checkout }
key: tests-need-local-postgres
kind: lesson
written_by: { type: agent, name: claude-code }
content_type: text/markdown
lifecycle: { expires_at: null, extended_by: write }
attributes: { vcs.pr: 482, ci.run_url: "https://ci.example/runs/123" }
---
Integration tests fail with `ECONNREFUSED 127.0.0.1:5432` unless Postgres
is already running. Start it before `pnpm test`:

    docker compose up -d db

The test setup does not start it for you.
The frontmatter is the envelope: address and key say where it's true, id is its identity, lifecycle says when it stops, and written_by answers the fork. The Markdown below it is the memory itself, and content_type tells a reader how to treat it. Anything else a tool needs goes in attributes, under a namespace other tools can ignore. The same record serialises to JSON just as well, for a tool that wants to send it over the wire.
Around that record, a spec would mirror OpenTelemetry's layers:
- Conventions: shared names for address levels (
global,project,repo,branch, and whatever monorepos need), for kinds, and for attribute namespaces (vcs.*,ci.*,agent.*), in one versioned registry. - A contract: a few operations (write, read, list, search, archive) with fixed inputs and outputs, exposed over MCP. Many memory servers now offer an MCP interface, but each exposes different tools with different meanings.
- Conformance tests in place of a reference implementation: round-trip a record and check nothing was lost, check that unknown attributes survive a rewrite, check that expiry behaves as stated.
What stays out matters as much: storage, ranking, embeddings, the user interface. That's where tools should compete. And the spec should live somewhere neutral, not in LoreKit's repo or any single vendor's.
What a skeptic would say
"You build a memory tool, so of course you want a standard shaped like it." Fair. It's why LoreKit is one row in the table rather than the template. If a shared spec looks different, LoreKit should adopt it anyway.
"MCP already is the standard." MCP standardises the call, not the record. OpenTelemetry needed a protocol and a data model. Memory needs both too.
"Shared memory is a prompt-injection channel." Yes. Anything an agent reads can steer it, and shared memory widens who gets to write it. A spec should make that visible: record who wrote each memory, allow signatures (Portable Memory already does), and let a record point at the code it depends on so a reader can check whether that code changed. No format makes poisoning impossible.
"Another standard won't fix fragmentation." That's xkcd 927, and it's the strongest objection. My answer is OpenTelemetry's: agreement came when existing projects merged, not when someone added another one. The work here is the same: take what the existing proposals and tools each got right, and agree on the parts they share.
Open questions
I don't know the answers to these, and I'd rather work them out in public:
- Which address levels? Monorepos want a level between
repoandbranch. Should levels be a fixed list or conventions? - Should forgetting be the default? Copilot forgets by default, LoreKit doesn't, and LangGraph extends life on read.
- Should a record point at the code it depends on? It's the best protection against stale memory, but it ties a record to a code host.
- Who should coordinate? A working group, a foundation, or a draft spec people send changes to?
If you build any of the tools in the table, or wrote one of the proposals, I'd like to compare notes. LoreKit's schema and on-disk format are MIT-licensed as one concrete input. To see real records, LoreKit's offline store writes plain Markdown files you can open, grep and diff:
npx @lorekit/cli installCompare them with what your other tools write, and tell me what a shared format would need that none of them have yet.