LLM Classification Is Feature Engineering
LLMs-as-classifiers, prompts applied to a context and returning a label, suck to work with. This is especially painful because they often perform pretty decently.
But let’s consider some of the things we’d want in a classifier and see how an LLM-as-classifier stacks up:
- Calibration / Threshold Control
- LLM verdicts are often hard labels; you can get token log probabilities but there is no mechanism for believing these to be well-calibrated. You can ask the LLM for its confidence and there’s no reason to suspect that to be well-calibrated either. As a related problem it’s then rather hard to trade off precision and recall with these labels in a principled way.
- Incorporating all available information
- LLMs work great with unstructured data but we often have nice structured data as well.
We can paste this into the prompt however the LLM doesn’t really need to use it.
Even for prose parts of the prompt we don’t know if the LLM actually used it or not1.
Frustrating to say the least and probably losing some signal.
The LLM has some prior information baked in which might be a poor fit for our distribution. For instance the LLM won’t know whether we’re testing on a population where our positive class is rare or an enriched population where our positive class is relatively prevalent. And I guess you can give it that context but now you’ve got to modify that for each new population and also, as in our first point, it’s not clear that this will be appropriately incorporated into the LLM’s judgement.
- Interpretability
- In some respects a LLM prompt is highly interpretable, after all it’s written in prose; unfortunately it’s not clear that we know exactly what’s going on within the LLM and what parts of the prompt are being followed correctly (or at all).
These failures are not the fault of the LLM: it’s not designed as a classifier and indeed has no mechanism for plausibly doing some of these things. But only because we’re thinking of things incorrectly…
With the proper framework that harnesses the LLM’s power we can get the power of the LLM with the convenience of stock ML algorithms. For a taste of what’s possible consider wrapping the LLM verdict with a simple logistic regression:
\[ p(y = 1 \mid x) = \sigma(\alpha + \beta \cdot LLM(x)) \]
Note that in the special case of \(\beta \rightarrow \infty\) this basically recovers our LLM classifier!! But that’s a dumb parameter selection policy. We should instead do our usual approach of estimating our parameters using some training data. This will then collapse into two cases and we just get the empirical estimates.
\[ p(y = k \mid LLM(x) = 1) = \frac{\sum_{i} I(y_{i} = k \text{ and } LLM(x_{i}) = 1)}{\sum_{i} I(LLM(x_{i}) = 1)} \]
Now let’s revisit our desiderata:
- Calibration / Threshold Control
- As just mentioned, just using the LLM prediction as a feature we get two predictions at the empirical proportions (and thus calibrated in expectation). As we add more features (see next) we will obviously get more unique points and, assuming our model is decently flexible, these should be approximately well-calibrated (and we have ways to improve that). And since we have actual probabilities out we can now choose our operating threshold to trade off precision and recall as needed.
- Incorporating all available information
- This is just a logistic regression so we can obviously add in other covariates. To adapt to the different baselines the logistic regression is fit to the training dataset and thus adapts to that baseline and covariate structure. We can even reweight the examples to try to target other distributions of interest.
- Interpretability
- We still have the problem of interpreting the LLM verdict itself but now we have a better sense of how that verdict is contributing to our final decision (especially if we have other covariates included).
We’ve basically recovered all of the nice properties we wanted from our model! Can we go even further?
LLM Classification is really good feature engineering
Suppose we are not pleased with the performance of our classifier: what should we do? In the LLM-as-classifier case our only option is to try messing with the prompt. This is an arcane undertaking about which advice abounds on the internet but wisdom is scarce. Best of luck to you.
From a ML point of view the way you make your model better is:
- Collecting more data
- Admittedly this is uncool: the allure of LLMs-as-classifiers is that you have a training-free methodology. So it’s disappointing that you need data for training purposes in this feature engineering paradigm. I’d argue though that this is less inconvenient than one might think. Like we’re going to need a test set in order to test model performance anyways (you were going to quantify your performance right?) so what’s a little more for training?
- Making your features better
- Making your features better is complex when editting prose. We can at least screen our features: if we believe that a feature should always lead to a positive we can empirically check this and debug appropriately. We can also evaluate the features themselves: we treat them as a secondary target (and recurse on making that classifier better).
- Creating more features
- You can use the residuals in your model to try and figure out how to improve your prompts not by meddling with wording but rather by considering a broader set of features. We might immediately consider taking the log probability of our verdict token; alternatively we can have multiple runs of our classifier (if we have reasoning before the verdicts those logprobs can go to 0 or 1). We can also get more features from the LLM itself by asking for subverdicts or other features.
- Improving your model architecture
- Finally model architecture is purely plug-and-play. Don’t like logistic regression, consider xgboost or a neural network. Heck have a rules based system implemented by the LLM for all I care. All are fair game.
Test Case: Irony Detection
Let’s make this more concrete using an example. We’ll use the SemEval 2018 Task 3 dataset2, a collection of 4618 tweets (3834 train / 784 test) labeled for irony by expert annotators. Irony is a natural fit for this post it’s an NLP task where an LLM clearly has real signal and we benefit from the worldly knowledge implicitly embedded in the LLM.
Our prompt asks the model to make a binary irony judgment, and we run it over all the tweets at once as a batch job:
from typing import Literal

from pydantic import BaseModel, Field

MODEL = "gemini-3.1-flash-lite"

PROMPT_TEMPLATE = """\
Irony is when someone says one thing but means another, often for \
humorous or critical effect. It can be subtle: a tweet might read as \
sincere at first glance but carry an ironic tone through word choice, \
context, or contrast.

Consider the following tweet and label it as "Ironic" or "Not".

{tweet}"""


class Verdict(BaseModel):
    reasoning: str = Field(
        description="Brief reasoning: what language or context suggests irony or sincerity."
    )
    verdict: Literal["Ironic", "Not"] = Field(
        description='Whether the tweet is ironic ("Ironic") or not ("Not").'
    )


def build_request(row_id: int, tweet: str) -> dict:
    return {
        "contents": [
            {"role": "user", "parts": [{"text": PROMPT_TEMPLATE.format(tweet=tweet)}]}
        ],
        "metadata": {"id": str(row_id)},
        "config": {
            "response_mime_type": "application/json",
            "response_schema": Verdict,
            "temperature": 0,
        },
    }
Performance
We get the following performance just from this prompt
| TPR | FNR | Brier Score | F1 (@0.5) |
|---|---|---|---|
| 0.965 | 0.035 | 0.259 | 0.747 |
It’s actually quite remarkable how well this does as one-shot. You wouldn’t expect this to be possible without learning which is the cool thing about LLMs. Of course it’s still pretty meh: the Brier score is quite bad as we don’t have calibration (indeed just random guessing gets us a Brier score of 0.25).
Desiderata
Calibration
We can do better with our logistic regression which achieves calibration (though note it doesn’t affect the ordering so F1 is the same).
| LLM verdict | Fitted P(Ironic) |
|---|---|
| Ironic | 0.687 |
| Not | 0.188 |
| TPR | FNR | Brier Score | F1 (@0.5) |
|---|---|---|---|
| 0.965 | 0.035 | 0.175 | 0.747 |
Adding Features
Let’s consider some additional LLM features. Firstly let’s take a quick look at our misclassifications (they’re the same from either model)
| tweet | target | verdict | reasoning |
|---|---|---|---|
| “I can’t breathe!” was chosen as the most notable quote of t… | Ironic | Not | The tweet presents a factual statement about a quote being selected for a list, … |
| 4:30 an opening my first beer now gonna be a long night/day | Not | Ironic | The tweet describes a situation of drinking early in the day as a ’long night/da… |
| crushes are great until you realize they’ll never be interes… | Ironic | Not | The tweet expresses a common, relatable sentiment about unrequited love. The use… |
| I guess my cat also lost 3 pounds when she went to the vet a… | Not | Ironic | The user is using hashtags related to fitness and weight loss to describe a cat’… |
| @yWTorres9 time to hit the books then | Ironic | Not | The tweet is a straightforward, literal suggestion to study, lacking any linguis… |
| “Twig” is now “Sprig”—3 sec limit on new social video plat… | Ironic | Not | The tweet uses a neutral, descriptive tone to report on a tech industry trend wi… |
| Luv this | Ironic | Not | The tweet is ambiguous; without additional context or visual cues, it is typical… |
| really, what else can a fish be besides a fish? @RBRNetwork1… | Not | Ironic | The tweet uses a rhetorical question to point out the obviousness of a statement… |
| @malesurvivor72 I think it’s a safe bet it won’t fit the cri… | Not | Ironic | The phrase ‘won’t fit the crime’ is a play on the common idiom ’the punishment f… |
| loyalty vs. self protection loyalty vs. self protection loya… | Not | Ironic | The repetitive, mantra-like structure suggests a cynical or weary observation ab… |
In light of this let’s modify our prompt as follows
from typing import Literal

from pydantic import BaseModel, Field

MODEL = "gemini-3.1-flash-lite"

PROMPT_TEMPLATE = """\
Analyse the following tweet along several dimensions.

Tweet: {tweet}

First, label it as "Ironic" or "Not" (irony is when the author says one \
thing but means another — not merely criticism or complaint). Then answer \
each question:
1. Is the tweet trying to be funny or humorous (regardless of whether it's ironic)?
2. Does the tweet describe a realistic, plausible situation or event?
3. Would you need to know the reply thread, current news, or other external \
context to understand the author's intent?
4. Does the tweet express a genuine complaint or frustration?
5. Does the tweet describe a negative or frustrating situation using \
positive or upbeat language (i.e. is there a mismatch between the situation \
and how it is described)?
6. Is the tweet self-deprecating — does the author make fun of or \
belittle themselves?
7. Does the tweet contain an explicit contrast or juxtaposition of two \
things (e.g. "X but Y", "while X, Y", "sure, X")?
8. Is the tweet a rhetorical question — a question not expecting a \
literal answer?
9. Does the tweet give what appears to be a compliment or praise but \
is actually critical or dismissive (a backhanded compliment)?
10. Is the tweet directed as criticism at a specific named person, \
organisation, or public figure?
11. Ignoring tone and word choice entirely: is the underlying situation \
described objectively negative or unfortunate (e.g. illness, failure, \
injustice, bad luck)?
12. Is the tweet making a direct, sincere critical or political point — \
i.e. the criticism is meant literally, not ironically? (A tweet can be \
critical and non-ironic.)
13. Does the author express approval, enthusiasm, or celebration of \
something that is clearly bad or undesirable (e.g. "love when X" where \
X is obviously awful)?
14. Does the author feign surprise or shock at something that is actually \
predictable, obvious, or expected (e.g. "shocked, just shocked", \
"who could have seen this coming")?
15. Does the tweet use mock enthusiasm — over-the-top positive language \
(exclamations, "amazing!", "so great!") applied to something bad or \
frustrating?
16. Does the tweet contain a pun, wordplay, or a deliberate double \
meaning unrelated to irony (the humour comes from the language itself, \
not from saying the opposite of what is meant)?
17. Is the tweet primarily about politics, politicians, government, \
elections, or political ideology?
18. Is the tweet primarily about a celebrity, athlete, sports team, \
or entertainment figure?
19. Is the tweet about the author's personal daily life, routine, or \
mundane situation (commute, weather, food, work, sleep)?"""


class Features(BaseModel):
    reasoning: str = Field(
        description="Brief reasoning covering the irony verdict and all nineteen dimensions."
    )
    verdict: Literal["Ironic", "Not"] = Field(
        description='Whether the tweet is ironic ("Ironic") or not ("Not").'
    )
    is_humorous: bool = Field(
        description="True if the tweet is trying to be funny or humorous."
    )
    realistic_situation: bool = Field(
        description="True if the tweet describes a realistic, plausible situation."
    )
    requires_context: bool = Field(
        description="True if understanding the author's intent requires external context."
    )
    is_complaint: bool = Field(
        description="True if the tweet expresses a genuine complaint or frustration."
    )
    sentiment_mismatch: bool = Field(
        description="True if the tweet describes a negative/frustrating situation using positive language."
    )
    is_self_deprecating: bool = Field(
        description="True if the author makes fun of or belittles themselves."
    )
    has_contrast: bool = Field(
        description="True if the tweet contains an explicit contrast or juxtaposition of two things."
    )
    is_rhetorical_question: bool = Field(
        description="True if the tweet is a rhetorical question not expecting a literal answer."
    )
    is_backhanded_compliment: bool = Field(
        description="True if the tweet gives apparent praise that is actually critical or dismissive."
    )
    targets_person_or_org: bool = Field(
        description="True if the tweet is directed as criticism at a specific named person, organisation, or public figure."
    )
    situation_is_negative: bool = Field(
        description="True if the underlying situation described is objectively negative or unfortunate, regardless of tone."
    )
    is_literal_criticism: bool = Field(
        description="True if the tweet makes a direct, sincere critical or political point (criticism is meant literally, not ironically)."
    )
    author_endorses_bad_outcome: bool = Field(
        description="True if the author expresses approval or celebration of something clearly bad or undesirable."
    )
    feigned_surprise: bool = Field(
        description="True if the author feigns shock or surprise at something predictable or obvious."
    )
    mock_enthusiasm: bool = Field(
        description="True if the tweet uses over-the-top positive language applied to something bad or frustrating."
    )
    is_pun_or_wordplay: bool = Field(
        description="True if the tweet contains a pun or wordplay where humour comes from the language itself rather than saying the opposite of what is meant."
    )
    is_political: bool = Field(
        description="True if the tweet is primarily about politics, politicians, government, elections, or political ideology."
    )
    is_celebrity_or_sports: bool = Field(
        description="True if the tweet is primarily about a celebrity, athlete, sports team, or entertainment figure."
    )
    is_mundane_daily_life: bool = Field(
        description="True if the tweet is about the author's personal daily life, routine, or mundane situation."
    )


def build_request(row_id: int, tweet: str) -> dict:
    return {
        "contents": [
            {"role": "user", "parts": [{"text": PROMPT_TEMPLATE.format(tweet=tweet)}]}
        ],
        "metadata": {"id": str(row_id)},
        "config": {
            "response_mime_type": "application/json",
            "response_schema": Features,
            "temperature": 0,
        },
    }
We’ll also start adding in some deterministic features that we can compute:
| Feature | What it measures |
|---|---|
| is_reply | Tweet starts with “@” (a reply) |
| has_url | Tweet contains a URL |
| tweet_length | Character length of the tweet |
| n_hashtags | Number of “#” characters |
| n_exclamations | Number of “!” characters |
| n_caps_words | Number of all-caps words (length > 1) |
| has_ellipsis | Tweet contains “…” |
| starts_with_quote | Tweet starts with a quotation mark |
| n_emoji | Number of emoji characters |
So do we see improvements? We compare three nested models: verdict only, verdict + all LLM features, verdict + all features (LLM + rule-based).
| Features | Brier | F1 (test) |
|---|---|---|
| Verdict only | 0.175 | 0.747 |
| + LLM features | 0.131 | 0.768 |
| + rule-based features | 0.127 | 0.779 |
We see a clear benefit from each level of additional features including the deterministic features which lie outside of the LLM.
Interpretability
The coefficient figure shows which features the model actually relies on, controlling for all others:
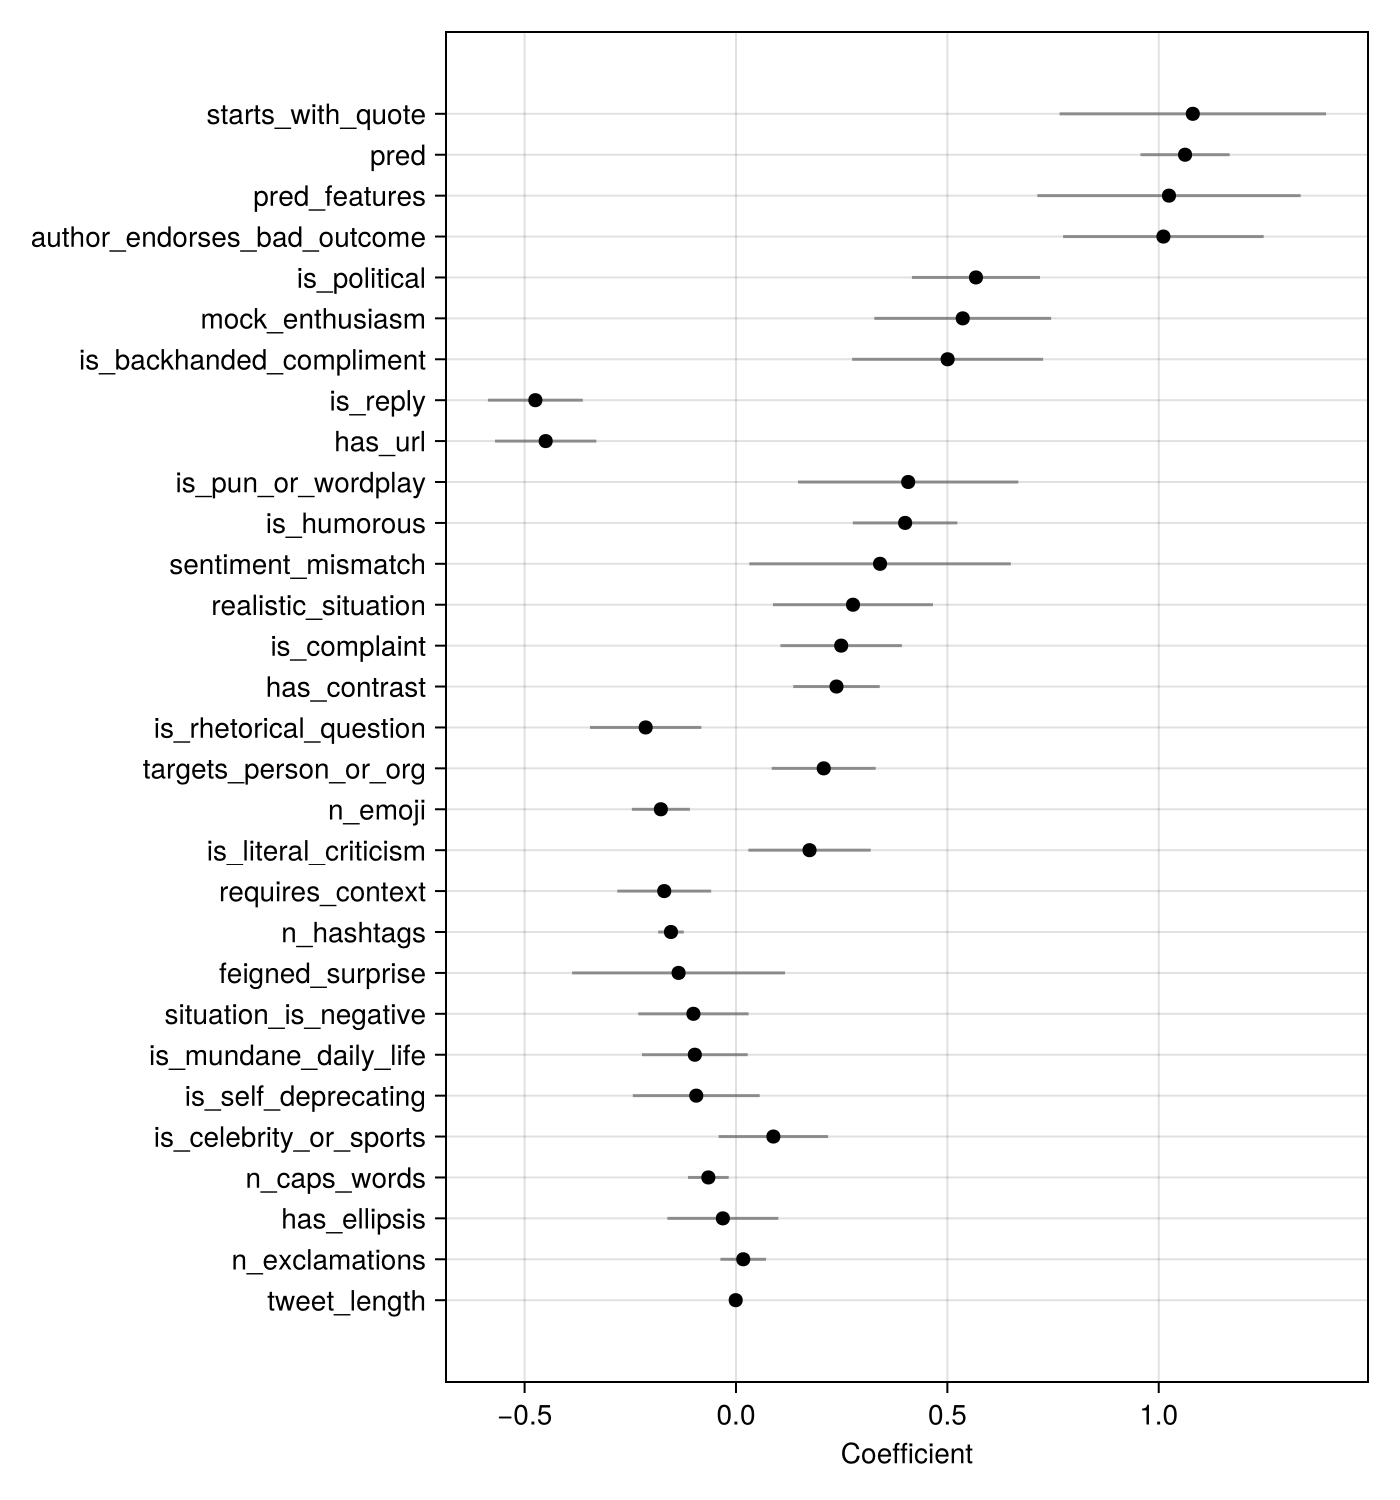
Figure 1: Logistic regression coefficients (± 1 SE), sorted by |coefficient|.
Comparison with published results
How does our approach compare to the published literature on this dataset?
Table 1: F1 scores on SemEval 2018 Task 3A test set.
| System | F1 |
|---|---|
| Random baseline | 0.373 |
| SVM + tf-idf (paper NRC baseline) | 0.589 |
| THU\_NGN (competition winner)3 | 0.705 |
| NTUA-SLP (post-competition LSTM + attention)4 | 0.786 |
| LLM hard label (this post) | 0.747 (0.712–0.778) |
| LLM + LR | 0.779 (0.746–0.81) |
We see that our initial LLM classifier beats the competition winner handily (0.747 vs 0.705). With the feature engineering perspective we have overlapping CIs with the post-competition state of the art, using nothing but a logistic regression on top of LLM-extracted features.
Conclusion
Getting LLMs into shape to reliably serve as classifiers is hard work but potentially highly impactful. There’s more and more research that relies on LLMs for classification: like the How People Use ChatGPT which uses LLMs to classify conversations with LLMs5 or the “slop-vestigation” of the Huggingface incident. We’re going to need to get high quality results out of these tools.
Fortunately, there’s a growing body of papers which are making this point.
- Han et al., “Large Language Models Can Automatically Engineer Features for Few-Shot Tabular Learning” (ICML 2024).
- Balek et al., “LLM-based feature generation from text for interpretable machine learning” (2024).
- Malberg, Mosca & Groh, “FELIX: Automatic and Interpretable Feature Engineering Using LLMs” (ECML PKDD 2024).
Personally I am interested in investigating agentic classifiers. Instead of a fixed feature set or class statement you empower the LLM to investigate itself. The LLM can use features of the investigative process as features when classifying: essentially grading itself on the rigor and comprehensiveness of the investigation. And with a reliable test set we can make statistically valid inferences on the results!